mirror of
https://github.com/wassname/geopandas.git
synced 2026-09-18 12:30:35 +08:00
API: expose sjoin_nearest, clip and overlay as methods (#2150)
Co-authored-by: Brendan Ward <bcward@astutespruce.com>
Co-authored-by: Joris Van den Bossche <jorisvandenbossche@gmail.com>
This commit is contained in:
 Martin Fleischmann
co-authored by
Brendan Ward
Joris Van den Bossche
Brendan Ward
Joris Van den Bossche
parent
087858c12a
commit
0a7eebf6d1
@@ -59,6 +59,24 @@ Aggregating and exploding
|
||||
GeoDataFrame.dissolve
|
||||
GeoDataFrame.explode
|
||||
|
||||
Spatial joins
|
||||
-------------
|
||||
|
||||
.. autosummary::
|
||||
:toctree: api/
|
||||
|
||||
GeoDataFrame.sjoin
|
||||
GeoDataFrame.sjoin_nearest
|
||||
|
||||
Overlay operations
|
||||
------------------
|
||||
|
||||
.. autosummary::
|
||||
:toctree: api/
|
||||
|
||||
GeoDataFrame.clip
|
||||
GeoDataFrame.overlay
|
||||
|
||||
Plotting
|
||||
--------
|
||||
|
||||
|
||||
@@ -144,6 +144,14 @@ Missing values
|
||||
GeoSeries.isna
|
||||
GeoSeries.notna
|
||||
|
||||
Overlay operations
|
||||
------------------
|
||||
|
||||
.. autosummary::
|
||||
:toctree: api/
|
||||
|
||||
GeoSeries.clip
|
||||
|
||||
Plotting
|
||||
--------
|
||||
|
||||
|
||||
@@ -91,21 +91,25 @@ In a Spatial Join, two geometry objects are merged based on their spatial relati
|
||||
|
||||
# Execute spatial join
|
||||
|
||||
cities_with_country = geopandas.sjoin(cities, countries, how="inner", predicate='intersects')
|
||||
cities_with_country = cities.sjoin(countries, how="inner", predicate='intersects')
|
||||
cities_with_country.head()
|
||||
|
||||
|
||||
GeoPandas provides two spatial-join functions:
|
||||
|
||||
- :func:`sjoin`: joins based on binary predicates (intersects, contains, etc.)
|
||||
- :func:`sjoin_nearest`: joins based on proximity, with the ability to set a maximum search radius.
|
||||
- :meth:`GeoDataFrame.sjoin`: joins based on binary predicates (intersects, contains, etc.)
|
||||
- :meth:`GeoDataFrame.sjoin_nearest`: joins based on proximity, with the ability to set a maximum search radius.
|
||||
|
||||
.. note::
|
||||
For historical reasons, both methods are also available as top-level functions :func:`sjoin` and :func:`sjoin_nearest`.
|
||||
It is recommended to use methods as the functions may be deprecated in the future.
|
||||
|
||||
Binary Predicate Joins
|
||||
~~~~~~~~~~~~~~~~~~~~~~
|
||||
|
||||
Binary predicate joins are available via :func:`sjoin`.
|
||||
Binary predicate joins are available via :meth:`GeoDataFrame.sjoin`.
|
||||
|
||||
:func:`sjoin` has two core arguments: ``how`` and ``predicate``.
|
||||
:meth:`GeoDataFrame.sjoin` has two core arguments: ``how`` and ``predicate``.
|
||||
|
||||
**predicate**
|
||||
|
||||
@@ -132,7 +136,7 @@ The `how` argument specifies the type of join that will occur and which geometry
|
||||
:class:`GeoDataFrame`. It accepts the following options:
|
||||
|
||||
* ``left``: use the index from the first (or `left_df`) :class:`GeoDataFrame` that you provide
|
||||
to :func:`sjoin`; retain only the `left_df` geometry column
|
||||
to :meth:`GeoDataFrame.sjoin`; retain only the `left_df` geometry column
|
||||
* ``right``: use index from second (or `right_df`); retain only the `right_df` geometry column
|
||||
* ``inner``: use intersection of index values from both :class:`GeoDataFrame`; retain only the `left_df` geometry column
|
||||
|
||||
@@ -143,9 +147,9 @@ point into a circle of appropriate radius, then intersect those buffered circles
|
||||
Nearest Joins
|
||||
~~~~~~~~~~~~~
|
||||
|
||||
Proximity-based joins can be done via :func:`sjoin_nearest`.
|
||||
Proximity-based joins can be done via :meth:`GeoDataFrame.sjoin_nearest`.
|
||||
|
||||
:func:`sjoin_nearest` shares the ``how`` argument with :func:`sjoin`, and
|
||||
:meth:`GeoDataFrame.sjoin_nearest` shares the ``how`` argument with :meth:`GeoDataFrame.sjoin`, and
|
||||
includes two additional arguments: ``max_distance`` and ``distance_col``.
|
||||
|
||||
**max_distance**
|
||||
|
||||
@@ -1,3 +1,5 @@
|
||||
.. currentmodule:: geopandas
|
||||
|
||||
.. ipython:: python
|
||||
:suppress:
|
||||
|
||||
@@ -14,22 +16,23 @@ When working with multiple spatial datasets -- especially multiple *polygon* or
|
||||
those datasets overlap (or don't overlap). These manipulations are often
|
||||
referred using the language of sets -- intersections, unions, and differences.
|
||||
These types of operations are made available in the *geopandas* library through
|
||||
the :func:`~geopandas.overlay` function.
|
||||
the :meth:`~geopandas.GeoDataFrame.overlay` method.
|
||||
|
||||
The basic idea is demonstrated by the graphic below but keep in mind that
|
||||
overlays operate at the DataFrame level, not on individual geometries, and the
|
||||
properties from both are retained. In effect, for every shape in the first
|
||||
:class:`~geopandas.GeoDataFrame`, this operation is executed against every other shape in the other
|
||||
properties from both are retained. In effect, for every shape in the left
|
||||
:class:`~geopandas.GeoDataFrame`, this operation is executed against every other shape in the right
|
||||
:class:`~geopandas.GeoDataFrame`:
|
||||
|
||||
.. image:: ../../_static/overlay_operations.png
|
||||
|
||||
**Source: QGIS Documentation**
|
||||
|
||||
(Note to users familiar with the *shapely* library: :func:`~geopandas.overlay` can be thought
|
||||
of as offering versions of the standard *shapely* set-operations that deal with
|
||||
the complexities of applying set operations to two *GeoSeries*. The standard
|
||||
*shapely* set-operations are also available as :class:`~geopandas.GeoSeries` methods.)
|
||||
.. note::
|
||||
Note to users familiar with the *shapely* library: :meth:`~geopandas.GeoDataFrame.overlay` can be thought
|
||||
of as offering versions of the standard *shapely* set-operations that deal with
|
||||
the complexities of applying set operations to two *GeoSeries*. The standard
|
||||
*shapely* set-operations are also available as :class:`~geopandas.GeoSeries` methods.
|
||||
|
||||
|
||||
The different Overlay operations
|
||||
@@ -57,16 +60,20 @@ These two GeoDataFrames have some overlapping areas:
|
||||
df2.plot(ax=ax, color='green', alpha=0.5);
|
||||
|
||||
We illustrate the different overlay modes with the above example.
|
||||
The :func:`~geopandas.overlay` function will determine the set of all individual geometries
|
||||
The :meth:`~geopandas.GeoDataFrame.overlay` method will determine the set of all individual geometries
|
||||
from overlaying the two input GeoDataFrames. This result covers the area covered
|
||||
by the two input GeoDataFrames, and also preserves all unique regions defined by
|
||||
the combined boundaries of the two GeoDataFrames.
|
||||
|
||||
.. note::
|
||||
For historical reasons, the overlay method is also available as a top-level function :func:`overlay`.
|
||||
It is recommended to use the method as the function may be deprecated in the future.
|
||||
|
||||
When using ``how='union'``, all those possible geometries are returned:
|
||||
|
||||
.. ipython:: python
|
||||
|
||||
res_union = geopandas.overlay(df1, df2, how='union')
|
||||
res_union = df1.overlay(df2, how='union')
|
||||
res_union
|
||||
|
||||
ax = res_union.plot(alpha=0.5, cmap='tab10')
|
||||
@@ -80,7 +87,7 @@ by both GeoDataFrames:
|
||||
|
||||
.. ipython:: python
|
||||
|
||||
res_intersection = geopandas.overlay(df1, df2, how='intersection')
|
||||
res_intersection = df1.overlay(df2, how='intersection')
|
||||
res_intersection
|
||||
|
||||
ax = res_intersection.plot(cmap='tab10')
|
||||
@@ -93,7 +100,7 @@ the geometries that are only part of one of the GeoDataFrames but not of both:
|
||||
|
||||
.. ipython:: python
|
||||
|
||||
res_symdiff = geopandas.overlay(df1, df2, how='symmetric_difference')
|
||||
res_symdiff = df1.overlay(df2, how='symmetric_difference')
|
||||
res_symdiff
|
||||
|
||||
ax = res_symdiff.plot(cmap='tab10')
|
||||
@@ -106,7 +113,7 @@ To obtain the geometries that are part of ``df1`` but are not contained in
|
||||
|
||||
.. ipython:: python
|
||||
|
||||
res_difference = geopandas.overlay(df1, df2, how='difference')
|
||||
res_difference = df1.overlay(df2, how='difference')
|
||||
res_difference
|
||||
|
||||
ax = res_difference.plot(cmap='tab10')
|
||||
@@ -119,7 +126,7 @@ but with the geometries obtained from overlaying ``df1`` with ``df2``:
|
||||
|
||||
.. ipython:: python
|
||||
|
||||
res_identity = geopandas.overlay(df1, df2, how='identity')
|
||||
res_identity = df1.overlay(df2, how='identity')
|
||||
res_identity
|
||||
|
||||
ax = res_identity.plot(cmap='tab10')
|
||||
@@ -146,7 +153,7 @@ First, we load the countries and cities example datasets and select :
|
||||
countries = countries.to_crs('epsg:3395')
|
||||
capitals = capitals.to_crs('epsg:3395')
|
||||
|
||||
To illustrate the :func:`~geopandas.overlay` function, consider the following case in which one
|
||||
To illustrate the :meth:`~geopandas.GeoDataFrame.overlay` method, consider the following case in which one
|
||||
wishes to identify the "core" portion of each country -- defined as areas within
|
||||
500km of a capital -- using a ``GeoDataFrame`` of countries and a
|
||||
``GeoDataFrame`` of capitals.
|
||||
@@ -171,7 +178,7 @@ To select only the portion of countries within 500km of a capital, we specify th
|
||||
|
||||
.. ipython:: python
|
||||
|
||||
country_cores = geopandas.overlay(countries, capitals, how='intersection')
|
||||
country_cores = countries.overlay(capitals, how='intersection')
|
||||
@savefig country_cores.png width=5in
|
||||
country_cores.plot(alpha=0.5, edgecolor='k', cmap='tab10');
|
||||
|
||||
@@ -179,7 +186,7 @@ Changing the "how" option allows for different types of overlay operations. For
|
||||
|
||||
.. ipython:: python
|
||||
|
||||
country_peripheries = geopandas.overlay(countries, capitals, how='difference')
|
||||
country_peripheries = countries.overlay(capitals, how='difference')
|
||||
@savefig country_peripheries.png width=5in
|
||||
country_peripheries.plot(alpha=0.5, edgecolor='k', cmap='tab10');
|
||||
|
||||
@@ -194,7 +201,7 @@ Changing the "how" option allows for different types of overlay operations. For
|
||||
keep_geom_type keyword
|
||||
----------------------
|
||||
|
||||
In default settings, :func:`~geopandas.overlay` returns only geometries of the same geometry type as df1
|
||||
In default settings, :meth:`~geopandas.GeoDataFrame.overlay` returns only geometries of the same geometry type as GeoDataFrame
|
||||
(left one) has, where Polygon and MultiPolygon is considered as a same type (other types likewise).
|
||||
You can control this behavior using ``keep_geom_type`` option, which is set to
|
||||
True by default. Once set to False, ``overlay`` will return all geometry types resulting from
|
||||
@@ -205,7 +212,7 @@ where two polygons intersects in a line or a point.
|
||||
More Examples
|
||||
-------------
|
||||
|
||||
A larger set of examples of the use of :func:`~geopandas.overlay` can be found `here <https://nbviewer.jupyter.org/github/geopandas/geopandas/blob/master/doc/source/gallery/overlays.ipynb>`_
|
||||
A larger set of examples of the use of :meth:`~geopandas.GeoDataFrame.overlay` can be found `here <https://nbviewer.jupyter.org/github/geopandas/geopandas/blob/master/doc/source/gallery/overlays.ipynb>`_
|
||||
|
||||
|
||||
|
||||
|
||||
@@ -2,7 +2,6 @@
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Overlays\n",
|
||||
"\n",
|
||||
@@ -16,20 +15,19 @@
|
||||
"not on individual geometries, and the properties from both are retained\n",
|
||||
"\n",
|
||||
"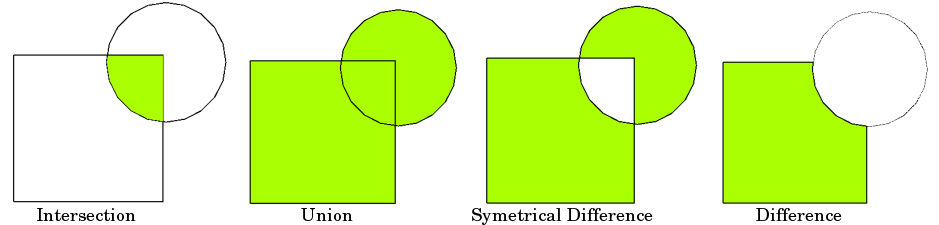"
|
||||
]
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"Now we can load up two GeoDataFrames containing (multi)polygon geometries..."
|
||||
]
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%matplotlib inline\n",
|
||||
"from shapely.geometry import Point\n",
|
||||
@@ -47,43 +45,44 @@
|
||||
" {'geometry': Point(x, y).buffer(10000), 'value1': x + y, 'value2': x - y}\n",
|
||||
" for x, y in zip(range(b[0], b[2], int((b[2] - b[0]) / N)),\n",
|
||||
" range(b[1], b[3], int((b[3] - b[1]) / N)))])"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"The first dataframe contains multipolygons of the NYC boros"
|
||||
]
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"polydf.plot()"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"And the second GeoDataFrame is a sequentially generated set of circles in the same geographic space. We'll plot these with a [different color palette](https://matplotlib.org/examples/color/colormaps_reference.html)."
|
||||
]
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"polydf2.plot(cmap='tab20b')"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"The `geopandas.tools.overlay` function takes three arguments:\n",
|
||||
"\n",
|
||||
@@ -99,104 +98,104 @@
|
||||
" 'symmetric_difference',\n",
|
||||
" 'difference']\n",
|
||||
"\n",
|
||||
"So let's identify the areas (and attributes) where both dataframes intersect using the `overlay` tool. "
|
||||
]
|
||||
"So let's identify the areas (and attributes) where both dataframes intersect using the `overlay` method. "
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from geopandas.tools import overlay\n",
|
||||
"newdf = overlay(polydf, polydf2, how=\"intersection\")\n",
|
||||
"newdf = polydf.overlay(polydf2, how=\"intersection\")\n",
|
||||
"newdf.plot(cmap='tab20b')"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"And take a look at the attributes; we see that the attributes from both of the original GeoDataFrames are retained. "
|
||||
]
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"polydf.head()"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"polydf2.head()"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"newdf.head()"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"Now let's look at the other `how` operations:"
|
||||
]
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"newdf = overlay(polydf, polydf2, how=\"union\")\n",
|
||||
"newdf = polydf.overlay(polydf2, how=\"union\")\n",
|
||||
"newdf.plot(cmap='tab20b')"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
],
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"newdf = overlay(polydf, polydf2, how=\"identity\")\n",
|
||||
"newdf.plot(cmap='tab20b')"
|
||||
]
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"source": [
|
||||
"newdf = polydf.overlay(polydf2, how=\"identity\")\n",
|
||||
"newdf.plot(cmap='tab20b')"
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"source": [
|
||||
"newdf = polydf.overlay(polydf2, how=\"symmetric_difference\")\n",
|
||||
"newdf.plot(cmap='tab20b')"
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {
|
||||
"tags": [
|
||||
"nbsphinx-thumbnail"
|
||||
]
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"newdf = overlay(polydf, polydf2, how=\"symmetric_difference\")\n",
|
||||
"newdf.plot(cmap='tab20b')"
|
||||
]
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"newdf = overlay(polydf, polydf2, how=\"difference\")\n",
|
||||
"newdf = polydf.overlay(polydf2, how=\"difference\")\n",
|
||||
"newdf.plot(cmap='tab20b')"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
@@ -220,4 +219,4 @@
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 4
|
||||
}
|
||||
}
|
||||
@@ -2,18 +2,17 @@
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Clip Vector Data with GeoPandas\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"Learn how to clip geometries to the boundary of a polygon geometry\n",
|
||||
"using GeoPandas."
|
||||
]
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"The example below shows you how to clip a set of vector geometries\n",
|
||||
"to the spatial extent / shape of another vector object. Both sets of geometries\n",
|
||||
@@ -33,33 +32,33 @@
|
||||
"be clipped to the total boundary of all polygons in clip object.\n",
|
||||
"</div>\n",
|
||||
"\n"
|
||||
]
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"Import Packages\n",
|
||||
"---------------\n",
|
||||
"\n",
|
||||
"To begin, import the needed packages.\n",
|
||||
"\n"
|
||||
]
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import matplotlib.pyplot as plt\n",
|
||||
"import geopandas\n",
|
||||
"from shapely.geometry import Polygon"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"Get or Create Example Data\n",
|
||||
"--------------------------\n",
|
||||
@@ -68,13 +67,12 @@
|
||||
"Additionally, a polygon is created with shapely and then converted into a\n",
|
||||
"GeoDataFrame with the same CRS as the GeoPandas world dataset.\n",
|
||||
"\n"
|
||||
]
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"capitals = geopandas.read_file(geopandas.datasets.get_path(\"naturalearth_cities\"))\n",
|
||||
"world = geopandas.read_file(geopandas.datasets.get_path(\"naturalearth_lowres\"))\n",
|
||||
@@ -85,22 +83,22 @@
|
||||
"# Create a custom polygon\n",
|
||||
"polygon = Polygon([(0, 0), (0, 90), (180, 90), (180, 0), (0, 0)])\n",
|
||||
"poly_gdf = geopandas.GeoDataFrame([1], geometry=[polygon], crs=world.crs)"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"Plot the Unclipped Data\n",
|
||||
"-----------------------\n",
|
||||
"\n"
|
||||
]
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"fig, (ax1, ax2) = plt.subplots(2, 1, figsize=(12, 8))\n",
|
||||
"world.plot(ax=ax1)\n",
|
||||
@@ -112,17 +110,18 @@
|
||||
"ax1.set_axis_off()\n",
|
||||
"ax2.set_axis_off()\n",
|
||||
"plt.show()"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"Clip the Data\n",
|
||||
"--------------\n",
|
||||
"\n",
|
||||
"When you call `clip`, the first object called is the object that will\n",
|
||||
"be clipped. The second object called is the clip extent. The returned output\n",
|
||||
"The object on which you call `clip` is the object that will\n",
|
||||
"be clipped. The object you pass is the clip extent. The returned output\n",
|
||||
"will be a new clipped GeoDataframe. All of the attributes for each returned\n",
|
||||
"geometry will be retained when you clip.\n",
|
||||
"\n",
|
||||
@@ -131,33 +130,28 @@
|
||||
"Note\n",
|
||||
"\n",
|
||||
"Recall that the data must be in the same CRS in order to use the\n",
|
||||
"`clip` function. If the data are not in the same CRS, be sure to use\n",
|
||||
"`clip` method. If the data are not in the same CRS, be sure to use\n",
|
||||
"the GeoPandas `GeoDataFrame.to_crs` method to ensure both datasets\n",
|
||||
"are in the same CRS.\n",
|
||||
"</div>\n",
|
||||
"\n"
|
||||
]
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"Clip the World Data\n",
|
||||
"--------------------\n",
|
||||
"\n"
|
||||
]
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"tags": [
|
||||
"nbsphinx-thumbnail"
|
||||
]
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"world_clipped = geopandas.clip(world, polygon)\n",
|
||||
"world_clipped = world.clip(polygon)\n",
|
||||
"\n",
|
||||
"# Plot the clipped data\n",
|
||||
"# The plot below shows the results of the clip function applied to the world\n",
|
||||
@@ -169,24 +163,36 @@
|
||||
"ax.set_title(\"World Clipped\", fontsize=20)\n",
|
||||
"ax.set_axis_off()\n",
|
||||
"plt.show()"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {
|
||||
"tags": [
|
||||
"nbsphinx-thumbnail"
|
||||
]
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"<div class=\"alert alert-info\">\n",
|
||||
" \n",
|
||||
"Note\n",
|
||||
"\n",
|
||||
"For historical reasons, the clip method is also available as a top-level function `geopandas.clip`.\n",
|
||||
"It is recommended to use the method as the function may be deprecated in the future.\n",
|
||||
"</div>\n",
|
||||
"\n",
|
||||
"Clip the Capitals Data\n",
|
||||
"----------------------\n",
|
||||
"\n"
|
||||
]
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"capitals_clipped = geopandas.clip(capitals, south_america)\n",
|
||||
"capitals_clipped = capitals.clip(south_america)\n",
|
||||
"\n",
|
||||
"# Plot the clipped data\n",
|
||||
"# The plot below shows the results of the clip function applied to the capital cities\n",
|
||||
@@ -196,7 +202,9 @@
|
||||
"ax.set_title(\"Capitals Clipped\", fontsize=20)\n",
|
||||
"ax.set_axis_off()\n",
|
||||
"plt.show()"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
@@ -220,4 +228,4 @@
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 4
|
||||
}
|
||||
}
|
||||
@@ -2,7 +2,6 @@
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Spatial Joins\n",
|
||||
"\n",
|
||||
@@ -13,11 +12,11 @@
|
||||
"A common use case might be a spatial join between a point layer and a polygon layer where you want to retain the point geometries and grab the attributes of the intersecting polygons.\n",
|
||||
"\n",
|
||||
"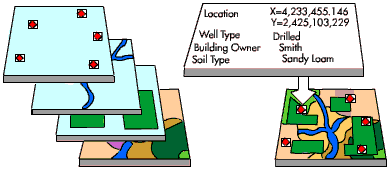"
|
||||
]
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"\n",
|
||||
"## Types of spatial joins\n",
|
||||
@@ -85,27 +84,25 @@
|
||||
" 0101000000F0D88AA0E1A4EEBF7052F7E5B115E9BF | 2 | 20\n",
|
||||
"(4 rows) \n",
|
||||
"```"
|
||||
]
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Spatial Joins between two GeoDataFrames\n",
|
||||
"\n",
|
||||
"Let's take a look at how we'd implement these using `GeoPandas`. First, load up the NYC test data into `GeoDataFrames`:"
|
||||
]
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%matplotlib inline\n",
|
||||
"from shapely.geometry import Point\n",
|
||||
"from geopandas import datasets, GeoDataFrame, read_file\n",
|
||||
"from geopandas.tools import overlay\n",
|
||||
"\n",
|
||||
"# NYC Boros\n",
|
||||
"zippath = datasets.get_path('nybb')\n",
|
||||
@@ -121,100 +118,101 @@
|
||||
"\n",
|
||||
"# Make sure they're using the same projection reference\n",
|
||||
"pointdf.crs = polydf.crs"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"pointdf"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"polydf"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"pointdf.plot()"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"polydf.plot()"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Joins"
|
||||
]
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from geopandas.tools import sjoin\n",
|
||||
"join_left_df = sjoin(pointdf, polydf, how=\"left\")\n",
|
||||
"join_left_df = pointdf.sjoin(polydf, how=\"left\")\n",
|
||||
"join_left_df\n",
|
||||
"# Note the NaNs where the point did not intersect a boro"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"join_right_df = sjoin(pointdf, polydf, how=\"right\")\n",
|
||||
"join_right_df = pointdf.sjoin(polydf, how=\"right\")\n",
|
||||
"join_right_df\n",
|
||||
"# Note Staten Island is repeated"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"join_inner_df = sjoin(pointdf, polydf, how=\"inner\")\n",
|
||||
"join_inner_df = pointdf.sjoin(polydf, how=\"inner\")\n",
|
||||
"join_inner_df\n",
|
||||
"# Note the lack of NaNs; dropped anything that didn't intersect"
|
||||
]
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"We're not limited to using the `intersection` binary predicate. Any of the `Shapely` geometry methods that return a Boolean can be used by specifying the `op` kwarg."
|
||||
]
|
||||
],
|
||||
"metadata": {}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"sjoin(pointdf, polydf, how=\"left\", op=\"within\")"
|
||||
]
|
||||
"pointdf.sjoin(polydf, how=\"left\", op=\"within\")"
|
||||
],
|
||||
"outputs": [],
|
||||
"metadata": {}
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
@@ -238,4 +236,4 @@
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 4
|
||||
}
|
||||
}
|
||||
@@ -1929,9 +1929,274 @@ individually so that features may have different properties
|
||||
------
|
||||
Every operation in GeoPandas is planar, i.e. the potential third
|
||||
dimension is not taken into account.
|
||||
|
||||
See also
|
||||
--------
|
||||
GeoDataFrame.sjoin_nearest : nearest neighbor join
|
||||
sjoin : equivalent top-level function
|
||||
"""
|
||||
return geopandas.sjoin(left_df=self, right_df=df, *args, **kwargs)
|
||||
|
||||
def sjoin_nearest(
|
||||
self,
|
||||
right,
|
||||
how="inner",
|
||||
max_distance=None,
|
||||
lsuffix="left",
|
||||
rsuffix="right",
|
||||
distance_col=None,
|
||||
):
|
||||
"""
|
||||
Spatial join of two GeoDataFrames based on the distance between their
|
||||
geometries.
|
||||
|
||||
Results will include multiple output records for a single input record
|
||||
where there are multiple equidistant nearest or intersected neighbors.
|
||||
|
||||
See the User Guide page
|
||||
https://geopandas.readthedocs.io/en/latest/docs/user_guide/mergingdata.html
|
||||
for more details.
|
||||
|
||||
|
||||
Parameters
|
||||
----------
|
||||
right : GeoDataFrame
|
||||
how : string, default 'inner'
|
||||
The type of join:
|
||||
|
||||
* 'left': use keys from left_df; retain only left_df geometry column
|
||||
* 'right': use keys from right_df; retain only right_df geometry column
|
||||
* 'inner': use intersection of keys from both dfs; retain only
|
||||
left_df geometry column
|
||||
|
||||
max_distance : float, default None
|
||||
Maximum distance within which to query for nearest geometry.
|
||||
Must be greater than 0.
|
||||
The max_distance used to search for nearest items in the tree may have a
|
||||
significant impact on performance by reducing the number of input
|
||||
geometries that are evaluated for nearest items in the tree.
|
||||
lsuffix : string, default 'left'
|
||||
Suffix to apply to overlapping column names (left GeoDataFrame).
|
||||
rsuffix : string, default 'right'
|
||||
Suffix to apply to overlapping column names (right GeoDataFrame).
|
||||
distance_col : string, default None
|
||||
If set, save the distances computed between matching geometries under a
|
||||
column of this name in the joined GeoDataFrame.
|
||||
|
||||
Examples
|
||||
--------
|
||||
>>> countries = geopandas.read_file(geopandas.datasets.get_\
|
||||
path("naturalearth_lowres"))
|
||||
>>> cities = geopandas.read_file(geopandas.datasets.get_path("naturalearth_citi\
|
||||
es"))
|
||||
>>> countries.head(2).name # doctest: +SKIP
|
||||
pop_est continent name \
|
||||
iso_a3 gdp_md_est geometry
|
||||
0 920938 Oceania Fiji FJI 8374.0 MULTI\
|
||||
POLYGON (((180.00000 -16.06713, 180.00000...
|
||||
1 53950935 Africa Tanzania TZA 150600.0 POLYG\
|
||||
ON ((33.90371 -0.95000, 34.07262 -1.05982...
|
||||
>>> cities.head(2).name # doctest: +SKIP
|
||||
name geometry
|
||||
0 Vatican City POINT (12.45339 41.90328)
|
||||
1 San Marino POINT (12.44177 43.93610)
|
||||
|
||||
>>> cities_w_country_data = cities.sjoin_nearest(countries)
|
||||
>>> cities_w_country_data[['name_left', 'name_right']].head(2) # doctest: +SKIP
|
||||
name_left geometry index_right pop_est continent n\
|
||||
ame_right iso_a3 gdp_md_est
|
||||
0 Vatican City POINT (12.45339 41.90328) 141 62137802 Europe \
|
||||
Italy ITA 2221000.0
|
||||
1 San Marino POINT (12.44177 43.93610) 141 62137802 Europe \
|
||||
Italy ITA 2221000.0
|
||||
|
||||
To include the distances:
|
||||
|
||||
>>> cities_w_country_data = cities.sjoin_nearest(countries, \
|
||||
distance_col="distances")
|
||||
>>> cities_w_country_data[["name_left", "name_right", \
|
||||
"distances"]].head(2) # doctest: +SKIP
|
||||
name_left name_right distances
|
||||
0 Vatican City Italy 0.0
|
||||
1 San Marino Italy 0.0
|
||||
|
||||
In the following example, we get multiple cities for Italy because all results
|
||||
are equidistant (in this case zero because they intersect).
|
||||
In fact, we get 3 results in total:
|
||||
|
||||
>>> countries_w_city_data = cities.sjoin_nearest(countries, \
|
||||
distance_col="distances", how="right")
|
||||
>>> italy_results = \
|
||||
countries_w_city_data[countries_w_city_data["name_left"] == "Italy"]
|
||||
>>> italy_results # doctest: +SKIP
|
||||
name_x name_y
|
||||
141 Vatican City Italy
|
||||
141 San Marino Italy
|
||||
141 Rome Italy
|
||||
|
||||
See also
|
||||
--------
|
||||
GeoDataFrame.sjoin : binary predicate joins
|
||||
sjoin_nearest : equivalent top-level function
|
||||
|
||||
Notes
|
||||
-----
|
||||
Since this join relies on distances, results will be innaccurate
|
||||
if your geometries are in a geographic CRS.
|
||||
|
||||
Every operation in GeoPandas is planar, i.e. the potential third
|
||||
dimension is not taken into account.
|
||||
"""
|
||||
return geopandas.sjoin_nearest(
|
||||
self,
|
||||
right,
|
||||
how=how,
|
||||
max_distance=max_distance,
|
||||
lsuffix=lsuffix,
|
||||
rsuffix=rsuffix,
|
||||
distance_col=distance_col,
|
||||
)
|
||||
|
||||
def clip(self, mask, keep_geom_type=False):
|
||||
"""Clip points, lines, or polygon geometries to the mask extent.
|
||||
|
||||
Both layers must be in the same Coordinate Reference System (CRS).
|
||||
The GeoDataFrame will be clipped to the full extent of the `mask` object.
|
||||
|
||||
If there are multiple polygons in mask, data from the GeoDataFrame will be
|
||||
clipped to the total boundary of all polygons in mask.
|
||||
|
||||
Parameters
|
||||
----------
|
||||
mask : GeoDataFrame, GeoSeries, (Multi)Polygon
|
||||
Polygon vector layer used to clip `gdf`.
|
||||
The mask's geometry is dissolved into one geometric feature
|
||||
and intersected with `gdf`.
|
||||
keep_geom_type : boolean, default False
|
||||
If True, return only geometries of original type in case of intersection
|
||||
resulting in multiple geometry types or GeometryCollections.
|
||||
If False, return all resulting geometries (potentially mixed types).
|
||||
|
||||
Returns
|
||||
-------
|
||||
GeoDataFrame
|
||||
Vector data (points, lines, polygons) from `gdf` clipped to
|
||||
polygon boundary from mask.
|
||||
|
||||
See also
|
||||
--------
|
||||
clip : equivalent top-level function
|
||||
|
||||
Examples
|
||||
--------
|
||||
Clip points (global cities) with a polygon (the South American continent):
|
||||
|
||||
>>> world = geopandas.read_file(
|
||||
... geopandas.datasets.get_path('naturalearth_lowres'))
|
||||
>>> south_america = world[world['continent'] == "South America"]
|
||||
>>> capitals = geopandas.read_file(
|
||||
... geopandas.datasets.get_path('naturalearth_cities'))
|
||||
>>> capitals.shape
|
||||
(202, 2)
|
||||
|
||||
>>> sa_capitals = capitals.clip(south_america)
|
||||
>>> sa_capitals.shape
|
||||
(12, 2)
|
||||
"""
|
||||
return geopandas.clip(self, mask=mask, keep_geom_type=keep_geom_type)
|
||||
|
||||
def overlay(self, right, how="intersection", keep_geom_type=None, make_valid=True):
|
||||
"""Perform spatial overlay between GeoDataFrames.
|
||||
|
||||
Currently only supports data GeoDataFrames with uniform geometry types,
|
||||
i.e. containing only (Multi)Polygons, or only (Multi)Points, or a
|
||||
combination of (Multi)LineString and LinearRing shapes.
|
||||
Implements several methods that are all effectively subsets of the union.
|
||||
|
||||
See the User Guide page :doc:`../../user_guide/set_operations` for details.
|
||||
|
||||
Parameters
|
||||
----------
|
||||
right : GeoDataFrame
|
||||
how : string
|
||||
Method of spatial overlay: 'intersection', 'union',
|
||||
'identity', 'symmetric_difference' or 'difference'.
|
||||
keep_geom_type : bool
|
||||
If True, return only geometries of the same geometry type the GeoDataFrame
|
||||
has, if False, return all resulting geometries. Default is None,
|
||||
which will set keep_geom_type to True but warn upon dropping
|
||||
geometries.
|
||||
make_valid : bool, default True
|
||||
If True, any invalid input geometries are corrected with a call to
|
||||
`buffer(0)`, if False, a `ValueError` is raised if any input geometries
|
||||
are invalid.
|
||||
|
||||
Returns
|
||||
-------
|
||||
df : GeoDataFrame
|
||||
GeoDataFrame with new set of polygons and attributes
|
||||
resulting from the overlay
|
||||
|
||||
Examples
|
||||
--------
|
||||
>>> from shapely.geometry import Polygon
|
||||
>>> polys1 = geopandas.GeoSeries([Polygon([(0,0), (2,0), (2,2), (0,2)]),
|
||||
... Polygon([(2,2), (4,2), (4,4), (2,4)])])
|
||||
>>> polys2 = geopandas.GeoSeries([Polygon([(1,1), (3,1), (3,3), (1,3)]),
|
||||
... Polygon([(3,3), (5,3), (5,5), (3,5)])])
|
||||
>>> df1 = geopandas.GeoDataFrame({'geometry': polys1, 'df1_data':[1,2]})
|
||||
>>> df2 = geopandas.GeoDataFrame({'geometry': polys2, 'df2_data':[1,2]})
|
||||
|
||||
>>> df1.overlay(df2, how='union')
|
||||
df1_data df2_data geometry
|
||||
0 1.0 1.0 POLYGON ((2.00000 2.00000, 2.00000 1.00000, 1....
|
||||
1 2.0 1.0 POLYGON ((2.00000 2.00000, 2.00000 3.00000, 3....
|
||||
2 2.0 2.0 POLYGON ((4.00000 4.00000, 4.00000 3.00000, 3....
|
||||
3 1.0 NaN POLYGON ((2.00000 0.00000, 0.00000 0.00000, 0....
|
||||
4 2.0 NaN MULTIPOLYGON (((3.00000 3.00000, 4.00000 3.000...
|
||||
5 NaN 1.0 MULTIPOLYGON (((2.00000 2.00000, 3.00000 2.000...
|
||||
6 NaN 2.0 POLYGON ((3.00000 5.00000, 5.00000 5.00000, 5....
|
||||
|
||||
>>> df1.overlay(df2, how='intersection')
|
||||
df1_data df2_data geometry
|
||||
0 1 1 POLYGON ((2.00000 2.00000, 2.00000 1.00000, 1....
|
||||
1 2 1 POLYGON ((2.00000 2.00000, 2.00000 3.00000, 3....
|
||||
2 2 2 POLYGON ((4.00000 4.00000, 4.00000 3.00000, 3....
|
||||
|
||||
>>> df1.overlay(df2, how='symmetric_difference')
|
||||
df1_data df2_data geometry
|
||||
0 1.0 NaN POLYGON ((2.00000 0.00000, 0.00000 0.00000, 0....
|
||||
1 2.0 NaN MULTIPOLYGON (((3.00000 3.00000, 4.00000 3.000...
|
||||
2 NaN 1.0 MULTIPOLYGON (((2.00000 2.00000, 3.00000 2.000...
|
||||
3 NaN 2.0 POLYGON ((3.00000 5.00000, 5.00000 5.00000, 5....
|
||||
|
||||
>>> df1.overlay(df2, how='difference')
|
||||
geometry df1_data
|
||||
0 POLYGON ((2.00000 0.00000, 0.00000 0.00000, 0.... 1
|
||||
1 MULTIPOLYGON (((3.00000 3.00000, 4.00000 3.000... 2
|
||||
|
||||
>>> df1.overlay(df2, how='identity')
|
||||
df1_data df2_data geometry
|
||||
0 1.0 1.0 POLYGON ((2.00000 2.00000, 2.00000 1.00000, 1....
|
||||
1 2.0 1.0 POLYGON ((2.00000 2.00000, 2.00000 3.00000, 3....
|
||||
2 2.0 2.0 POLYGON ((4.00000 4.00000, 4.00000 3.00000, 3....
|
||||
3 1.0 NaN POLYGON ((2.00000 0.00000, 0.00000 0.00000, 0....
|
||||
4 2.0 NaN MULTIPOLYGON (((3.00000 3.00000, 4.00000 3.000...
|
||||
|
||||
See also
|
||||
--------
|
||||
GeoDataFrame.sjoin : spatial join
|
||||
overlay : equivalent top-level function
|
||||
|
||||
Notes
|
||||
------
|
||||
Every operation in GeoPandas is planar, i.e. the potential third
|
||||
dimension is not taken into account.
|
||||
"""
|
||||
return geopandas.overlay(
|
||||
self, right, how=how, keep_geom_type=keep_geom_type, make_valid=make_valid
|
||||
)
|
||||
|
||||
|
||||
def _dataframe_set_geometry(self, col, drop=False, inplace=False, crs=None):
|
||||
if inplace:
|
||||
|
||||
@@ -12,6 +12,7 @@ from shapely.geometry.base import BaseGeometry
|
||||
from geopandas.base import GeoPandasBase, _delegate_property
|
||||
from geopandas.plotting import plot_series
|
||||
from geopandas.explore import _explore_geoseries
|
||||
import geopandas
|
||||
|
||||
from . import _compat as compat
|
||||
from ._decorator import doc
|
||||
@@ -1296,3 +1297,51 @@ e": "Feature", "properties": {}, "geometry": {"type": "Point", "coordinates": [3
|
||||
stacklevel=2,
|
||||
)
|
||||
return self.difference(other)
|
||||
|
||||
def clip(self, mask, keep_geom_type=False):
|
||||
"""Clip points, lines, or polygon geometries to the mask extent.
|
||||
|
||||
Both layers must be in the same Coordinate Reference System (CRS).
|
||||
The GeoSeries will be clipped to the full extent of the `mask` object.
|
||||
|
||||
If there are multiple polygons in mask, data from the GeoSeries will be
|
||||
clipped to the total boundary of all polygons in mask.
|
||||
|
||||
Parameters
|
||||
----------
|
||||
mask : GeoDataFrame, GeoSeries, (Multi)Polygon
|
||||
Polygon vector layer used to clip `gdf`.
|
||||
The mask's geometry is dissolved into one geometric feature
|
||||
and intersected with `gdf`.
|
||||
keep_geom_type : boolean, default False
|
||||
If True, return only geometries of original type in case of intersection
|
||||
resulting in multiple geometry types or GeometryCollections.
|
||||
If False, return all resulting geometries (potentially mixed-types).
|
||||
|
||||
Returns
|
||||
-------
|
||||
GeoSeries
|
||||
Vector data (points, lines, polygons) from `gdf` clipped to
|
||||
polygon boundary from mask.
|
||||
|
||||
See also
|
||||
--------
|
||||
clip : top-level function for clip
|
||||
|
||||
Examples
|
||||
--------
|
||||
Clip points (global cities) with a polygon (the South American continent):
|
||||
|
||||
>>> world = geopandas.read_file(
|
||||
... geopandas.datasets.get_path('naturalearth_lowres'))
|
||||
>>> south_america = world[world['continent'] == "South America"]
|
||||
>>> capitals = geopandas.read_file(
|
||||
... geopandas.datasets.get_path('naturalearth_cities'))
|
||||
>>> capitals.shape
|
||||
(202, 2)
|
||||
|
||||
>>> sa_capitals = capitals.geometry.clip(south_america)
|
||||
>>> sa_capitals.shape
|
||||
(12,)
|
||||
"""
|
||||
return geopandas.clip(self, mask=mask, keep_geom_type=keep_geom_type)
|
||||
|
||||
@@ -10,7 +10,7 @@ import pandas as pd
|
||||
import pyproj
|
||||
from pyproj import CRS
|
||||
from pyproj.exceptions import CRSError
|
||||
from shapely.geometry import Point
|
||||
from shapely.geometry import Point, Polygon
|
||||
|
||||
import geopandas
|
||||
import geopandas._compat as compat
|
||||
@@ -25,6 +25,36 @@ import pytest
|
||||
|
||||
|
||||
PYPROJ_LT_3 = LooseVersion(pyproj.__version__) < LooseVersion("3")
|
||||
TEST_NEAREST = compat.PYGEOS_GE_010 and compat.USE_PYGEOS
|
||||
pandas_133 = pd.__version__ == LooseVersion("1.3.3")
|
||||
|
||||
|
||||
@pytest.fixture
|
||||
def dfs(request):
|
||||
s1 = GeoSeries(
|
||||
[
|
||||
Polygon([(0, 0), (2, 0), (2, 2), (0, 2)]),
|
||||
Polygon([(2, 2), (4, 2), (4, 4), (2, 4)]),
|
||||
]
|
||||
)
|
||||
s2 = GeoSeries(
|
||||
[
|
||||
Polygon([(1, 1), (3, 1), (3, 3), (1, 3)]),
|
||||
Polygon([(3, 3), (5, 3), (5, 5), (3, 5)]),
|
||||
]
|
||||
)
|
||||
df1 = GeoDataFrame({"col1": [1, 2], "geometry": s1})
|
||||
df2 = GeoDataFrame({"col2": [1, 2], "geometry": s2})
|
||||
return df1, df2
|
||||
|
||||
|
||||
@pytest.fixture(
|
||||
params=["union", "intersection", "difference", "symmetric_difference", "identity"]
|
||||
)
|
||||
def how(request):
|
||||
if pandas_133 and request.param in ["symmetric_difference", "identity", "union"]:
|
||||
pytest.xfail("Regression in pandas 1.3.3 (GH #2101)")
|
||||
return request.param
|
||||
|
||||
|
||||
class TestDataFrame:
|
||||
@@ -794,6 +824,59 @@ class TestDataFrame:
|
||||
result = left.sjoin(right, how=how, predicate=predicate)
|
||||
assert_geodataframe_equal(result, expected)
|
||||
|
||||
@pytest.mark.parametrize("how", ["left", "inner", "right"])
|
||||
@pytest.mark.parametrize("max_distance", [None, 1])
|
||||
@pytest.mark.parametrize("distance_col", [None, "distance"])
|
||||
@pytest.mark.skipif(
|
||||
not TEST_NEAREST,
|
||||
reason=(
|
||||
"PyGEOS >= 0.10.0"
|
||||
" must be installed and activated via the geopandas.compat module to"
|
||||
" test sjoin_nearest"
|
||||
),
|
||||
)
|
||||
def test_sjoin_nearest(self, how, max_distance, distance_col):
|
||||
"""
|
||||
Basic test for availability of the GeoDataFrame method. Other
|
||||
sjoin tests are located in /tools/tests/test_sjoin.py
|
||||
"""
|
||||
left = read_file(geopandas.datasets.get_path("naturalearth_cities"))
|
||||
right = read_file(geopandas.datasets.get_path("naturalearth_lowres"))
|
||||
|
||||
expected = geopandas.sjoin_nearest(
|
||||
left, right, how=how, max_distance=max_distance, distance_col=distance_col
|
||||
)
|
||||
result = left.sjoin_nearest(
|
||||
right, how=how, max_distance=max_distance, distance_col=distance_col
|
||||
)
|
||||
assert_geodataframe_equal(result, expected)
|
||||
|
||||
@pytest.mark.skip_no_sindex
|
||||
def test_clip(self):
|
||||
"""
|
||||
Basic test for availability of the GeoDataFrame method. Other
|
||||
clip tests are located in /tools/tests/test_clip.py
|
||||
"""
|
||||
left = read_file(geopandas.datasets.get_path("naturalearth_cities"))
|
||||
world = read_file(geopandas.datasets.get_path("naturalearth_lowres"))
|
||||
south_america = world[world["continent"] == "South America"]
|
||||
|
||||
expected = geopandas.clip(left, south_america)
|
||||
result = left.clip(south_america)
|
||||
assert_geodataframe_equal(result, expected)
|
||||
|
||||
@pytest.mark.skip_no_sindex
|
||||
def test_overlay(self, dfs, how):
|
||||
"""
|
||||
Basic test for availability of the GeoDataFrame method. Other
|
||||
overlay tests are located in tests/test_overlay.py
|
||||
"""
|
||||
df1, df2 = dfs
|
||||
|
||||
expected = geopandas.overlay(df1, df2, how=how)
|
||||
result = df1.overlay(df2, how=how)
|
||||
assert_geodataframe_equal(result, expected)
|
||||
|
||||
|
||||
def check_geodataframe(df, geometry_column="geometry"):
|
||||
assert isinstance(df, GeoDataFrame)
|
||||
|
||||
@@ -20,7 +20,7 @@ from shapely.geometry import (
|
||||
)
|
||||
from shapely.geometry.base import BaseGeometry
|
||||
|
||||
from geopandas import GeoSeries, GeoDataFrame
|
||||
from geopandas import GeoSeries, GeoDataFrame, read_file, datasets, clip
|
||||
from geopandas._compat import PYPROJ_LT_3, ignore_shapely2_warnings
|
||||
from geopandas.array import GeometryArray, GeometryDtype
|
||||
from geopandas.testing import assert_geoseries_equal
|
||||
@@ -323,6 +323,16 @@ class TestSeries:
|
||||
def test_to_wkt(self):
|
||||
assert_series_equal(pd.Series([self.t1.wkt, self.sq.wkt]), self.g1.to_wkt())
|
||||
|
||||
@pytest.mark.skip_no_sindex
|
||||
def test_clip(self):
|
||||
left = read_file(datasets.get_path("naturalearth_cities"))
|
||||
world = read_file(datasets.get_path("naturalearth_lowres"))
|
||||
south_america = world[world["continent"] == "South America"]
|
||||
|
||||
expected = clip(left.geometry, south_america)
|
||||
result = left.geometry.clip(south_america)
|
||||
assert_geoseries_equal(result, expected)
|
||||
|
||||
def test_from_xy_points(self):
|
||||
x = self.landmarks.x.values
|
||||
y = self.landmarks.y.values
|
||||
|
||||
@@ -84,6 +84,11 @@ def clip(gdf, mask, keep_geom_type=False):
|
||||
Vector data (points, lines, polygons) from `gdf` clipped to
|
||||
polygon boundary from mask.
|
||||
|
||||
See also
|
||||
--------
|
||||
GeoDataFrame.clip : equivalent GeoDataFrame method
|
||||
GeoSeries.clip : equivalent GeoSeries method
|
||||
|
||||
Examples
|
||||
--------
|
||||
Clip points (global cities) with a polygon (the South American continent):
|
||||
|
||||
@@ -218,6 +218,7 @@ def overlay(df1, df2, how="intersection", keep_geom_type=None, make_valid=True):
|
||||
See also
|
||||
--------
|
||||
sjoin : spatial join
|
||||
GeoDataFrame.overlay : equivalent method
|
||||
|
||||
Notes
|
||||
------
|
||||
|
||||
@@ -499,6 +499,7 @@ countries_w_city_data[countries_w_city_data["name_left"] == "Italy"]
|
||||
See also
|
||||
--------
|
||||
sjoin : binary predicate joins
|
||||
GeoDataFrame.sjoin_nearest : equivalent method
|
||||
|
||||
Notes
|
||||
-----
|
||||
|
||||
Reference in New Issue
Block a user